
An API That Gets YouTube Transcripts When Single-Library Tools Fail
A transcript extraction service that handles every YouTube URL format, caches repeat requests, and falls back to a second extractor when the first one fails.
4
URL Formats Supported
Standard, shortened, Shorts, and embedded
99%+
Retrieval Success Rate
Dual-fallback system with yt-dlp backup
<10ms
Cached Response Time
In-memory caching for repeat requests
The Challenge
Content analysis tools, accessibility services, AI training pipelines, and educational platforms all need reliable programmatic access to YouTube transcripts.
Getting that access reliably is harder than it looks.
Why existing solutions break
Four URL formats. YouTube has at least four (standard, shortened, Shorts, embedded), and most libraries handle only one or two
Missing transcripts. Not every video has a transcript, and the failure modes are inconsistent and poorly documented
Rate limiting. YouTube aggressively rate-limits transcript requests, which turns into cascading failures in production applications
Fragile dependencies. Single-library solutions break whenever YouTube changes their internal APIs, which happens frequently
What developers wanted was one call that returns a transcript, or a clear "not available" response, so they could move on without handling any of this themselves.
Our Solution
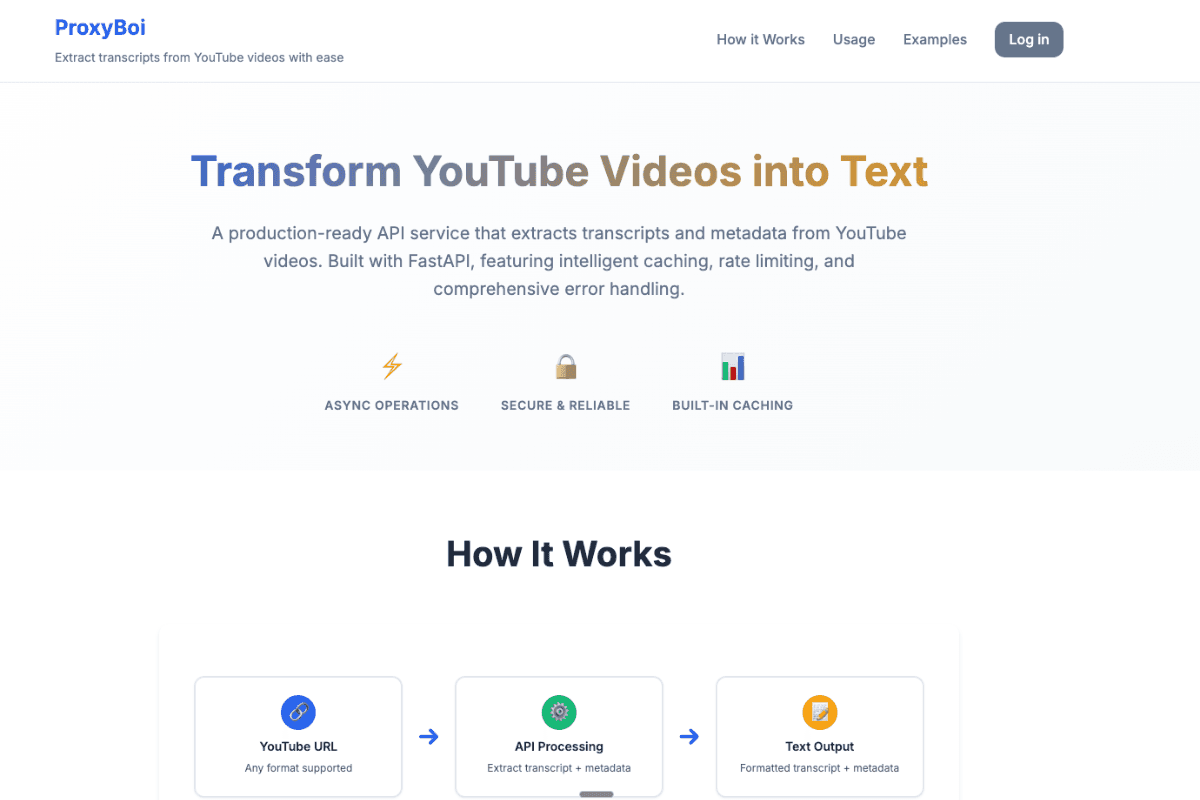
ProxyBoi is a production-ready FastAPI service that extracts YouTube transcripts using a dual-fallback architecture, with a second extraction path sitting behind the first.
Dual-fallback system
The primary path uses the YouTube Transcript API, which is the faster of the two. When it fails on missing captions, geo-restrictions or format issues, the service falls back to yt-dlp, which extracts by a different route. Between the two, ProxyBoi returns transcripts for videos where a single-library solution gives up.
URL handling
A unified URL parser normalizes all four YouTube URL formats into a canonical video ID before extraction. Standard watch URLs, youtu.be shortlinks, Shorts URLs, and embedded URLs all work identically.
Production features
In-memory caching. Repeat requests resolve in under 10ms, which reduces load and cost
Configurable rate limiting. Built-in throttling, 10 req/min by default, keeps YouTube from blocking the service
Rich metadata. Returns transcript text plus video title, channel, categories, and duration
API key authentication. Access control for multi-tenant usage
Docker-ready. Single container deployment with environment-based configuration
Our Approach
We kept ProxyBoi narrow. It has one job, which is returning the transcript for a given YouTube URL.
Architecture
We chose FastAPI for its async-first design. Extraction requests can take several seconds, so a request waiting on YouTube would otherwise hold up the ones behind it. That matters for API consumers processing batches of videos.
Reliability-first design
The dual-fallback pattern was the main architectural decision. No single extraction method covers every video, so we run two. The YouTube Transcript API handles the common cases quickly and yt-dlp catches everything else. Callers never see which path ran, since the response format is the same either way.
Testing against real videos
We tested against hundreds of real YouTube videos, covering auto-generated captions, multiple language tracks, age-restricted content, Shorts, live stream archives, and videos with captions disabled. Every failure we found became a test case and a change to the extraction logic.
Results & Outcomes
ProxyBoi is running in production powering content analysis tools, AI training data pipelines, accessibility services, and educational platforms.
Reliability at scale
The dual-fallback architecture reaches 99%+ transcript retrieval success rates, against single-library approaches that typically fail on 10 to 15% of videos because of format edge cases and missing caption tracks.
Developer experience
Integration takes minutes. A single REST endpoint accepts any YouTube URL format and returns structured transcript data with metadata, and the Docker deployment model lets teams self-host with zero external dependencies.
Performance
Cached responses resolve in under 10ms. First-request latency depends on video length, and the async architecture keeps the service responsive under concurrent load. Rate limiting keeps the service from tripping upstream throttling.
Use cases in production
Content analysis and summarization tools
AI/ML training data extraction
Accessibility services providing searchable video transcripts
Educational platforms converting lectures to study materials
Video SEO tools analyzing competitor content
Client Testimonial
“We tried three other transcript APIs before ProxyBoi. They all choked on edge cases: Shorts URLs, missing captions, rate limits. ProxyBoi just works. We integrated it in an afternoon and haven't thought about it since.”
Project
Engagement
Focused solo-developer sprint
Services
Ready for results like these?
See how we achieved 4 URL formats supported, and what we can do for you.
Start a Conversation